

Artificial intelligence has accelerated at a pace rarely seen in technology, and much of that progress is tied directly to advances in specialized hardware.
Two processor types sit at the center of AI:
Graphics Processing Units (GPUs) driven largely by NVIDIA
Tensor Processing Units (TPUs) designed and deployed by Google
Both accelerate the core math behind machine learning, but they approach the problem from fundamentally different directions.
To understand their impact on training, inference, and deployment, it’s essential to look at what each chip does best and where each falls short.
I wanna thank you in advance for reading this article!
GPUs: The flexible workhorse of AI
GPUs were first designed for video games.
They are made of thousands of tiny processing units (called cores) that can do many small calculations at the exact same time. This ability, doing huge amounts of math very quickly, is also exactly what modern AI needs.
Deep learning models rely heavily on matrix multiplications, which simply means multiplying large tables of numbers. GPUs are exceptionally good at that.
NVIDIA noticed this early and built a special software system called CUDA.
What is CUDA?
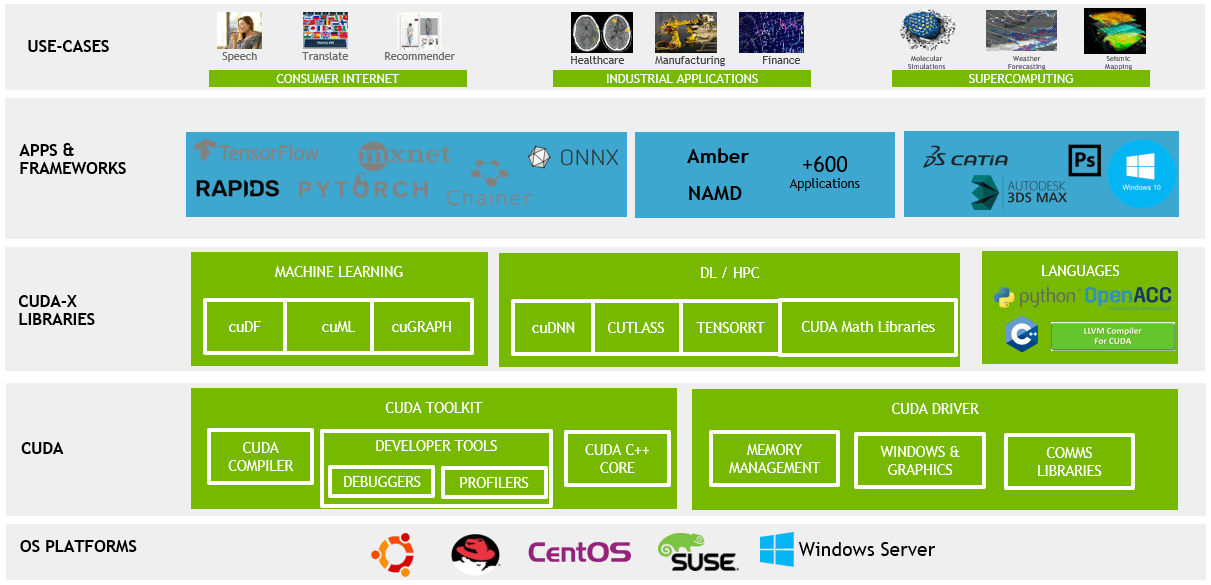
CUDA is a software platform that lets programmers tell a GPU exactly what to do.
Here’s what that means in plain English:
Normally, a computer’s processor (the CPU) decides how the computer runs programs.
CUDA lets software developers write programs that run directly on the GPU instead of the CPU.
This gives the GPU much more control and makes it useful for things far beyond gaming, especially AI.
CUDA stands for Compute Unified Device Architecture, but the name isn’t important. What matters is that it became a full ecosystem: tools, libraries, and programs built by NVIDIA to make GPUs the best option for AI.
Because of CUDA, researchers can build new AI models without having to design new hardware.
If you enjoy this article, subscribe or upgrade if you want more!
